Mysql- Explain
Explain含义
Explain是SQL分析工具中非常重要的一个功能,它可以模拟优化器执行查询语句,帮助我们理解查询是如何执行的;分析查询执行计划可以帮助我们发现查询瓶颈,优化查询性能。
Explain作用
- 表的读取顺序
- SQL执行时查询操作类型
- 可以使用那些索引
- 世纪使用那些索引
- 每张表有多少行记录被扫描
- SQL语句性能分析
Explain用法
Mysql5.7版本之前,使用Explain Extended在Explain的基础上额外多返回filtered列与extra列
Explain Extended select * from users;
Mysql5.7版本之前,使用Explain Partitions在Explain的基础上额外多返回partitions列
Explain Partitions select * from users;
Mysql5.7版本引入了这两个特性,直接使用Explain关键字可以讲partitions、filtered、extra列直接查询出来
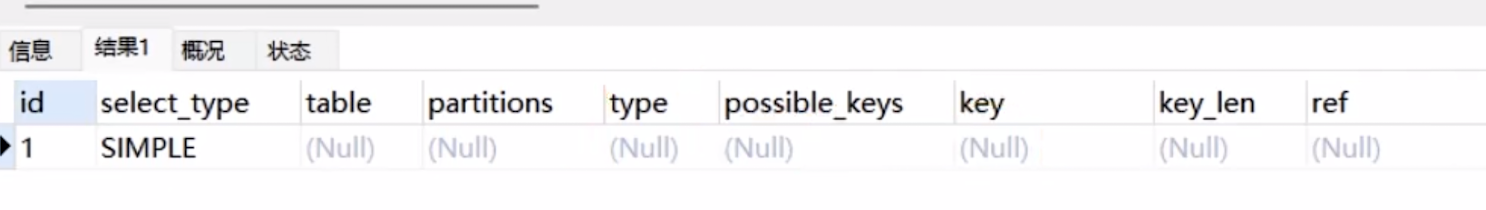
Explain语句返回列的各列含义
| 列名 | 含义 |
|---|---|
| id | 每个select都有一个对一个的ID,并且是从1开始自增的 |
| select_type | 查询语句执行的查询操作类型 |
| table | 表名 |
| partitions | 表分区情况 |
| type | 查询所用到的访问类型 |
| possible_keys | 可能用到的索引 |
| key | 实际查询用到的索引 |
| key_len | 所使用到的索引长度 |
| ref | 使用到索引时,与索引进行等值匹配到列或者常量 |
| rows | 预计扫描的行数(索引行数或者表记录行数) |
| filtered | 表示符合查询条件的数据百分比 |
| Extra | SQL执行的额外信息 |
Explain返回列详解
id
每个select都有一个对应的id,并且是从1开始自增的
- 如果id序号相同,从上往下执行
- 如果id序号不同,序号大的先执行
- 如果两种都存在,先执行序号大,在同级从上往下执行。
- 如果是NULL,最后执行。表示结果集,并且不需要使用它来进行查询。
Select_type
simple:简单select,不包括union与子查询
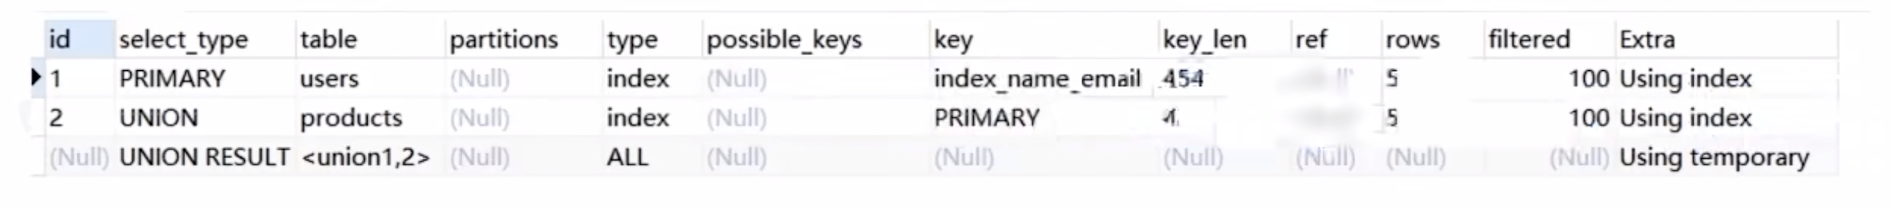
primary:复杂查询中最外层查询,比如使用union或union all时,id为1的记录的select_type通常是primary
explain
select id from users
union
select id from products;
Subquery: 指在select语句中出现的字查询语句,结果不依赖于外部查询(不在from语句中)
explain
select orders.*, (select name from products where id = 1) from orders;

dependent subquery: 指在select语句中出现的查询语句,结果依赖于外部查询
explain
select orders.* (select name from products where products.id = orders.user_id) from orders;
derived: 派生表,在from子句的查询语句,表示从外部数据源中推导出来的,而不是从select语句中的其他列中选择出来的。
set session optimizer_switch='derived_merge=off'; # 关闭mysql5.7对衍生表合并优化

explain
select * from (select user_id from orders where id = 1) as temp;

set session optimizer_switch='derived_merge=on'; # 关闭mysql5.7对衍生表合并优化
union: 分union与union all两种,若第二个select 出现在union之后,则被标记为union;如果union被from子句的字查询包含,那么第一个select会被标记为derived;union会针对相对的结果进行去重,union all不会进行去重处理。
explain
select * from (
select id from products where price = 10
  union
select id from orders where user_id in(1,3)
  union
select id from users where name = 'zx'
) as temp;
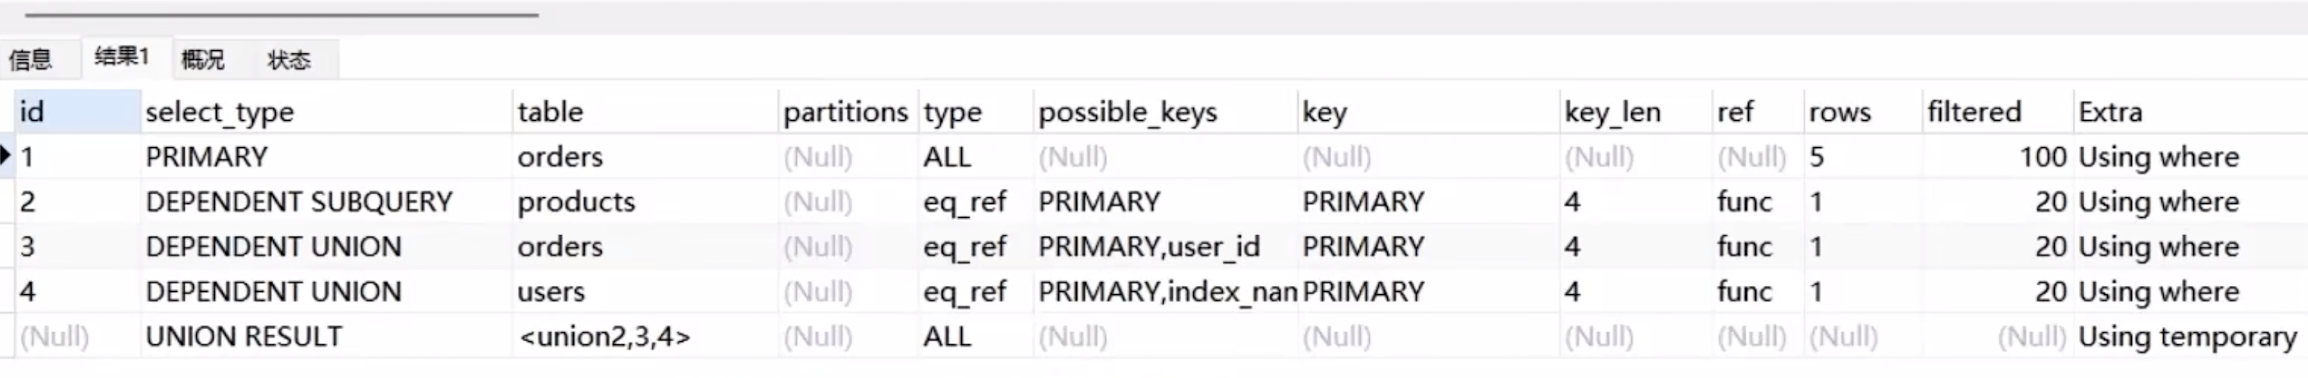
dependent union: 当union作为字查询时,其中第一个union为dependent subquery, 第二个union为dependent union。
explain
select * from orders where id in(
select id from products where price = 10
  union
select id from orders where user_id= 2
  union
select id from users where name = 'zx'
);
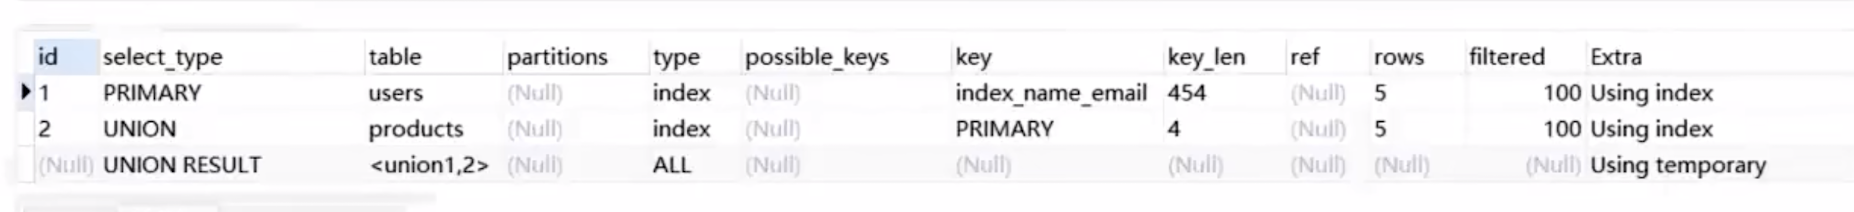
union result: 如果两个查询中有相同的列值,则会对这些值进行去重
explain
select id from users
union
select id from products;
type
查询所使用到到访问类型,效率从高到低为:system->const-> eq ref -> ref -> fulltext -> ref or null -> range -> index -> All, 一般来说保证range级别,最好能达到ref级别
system
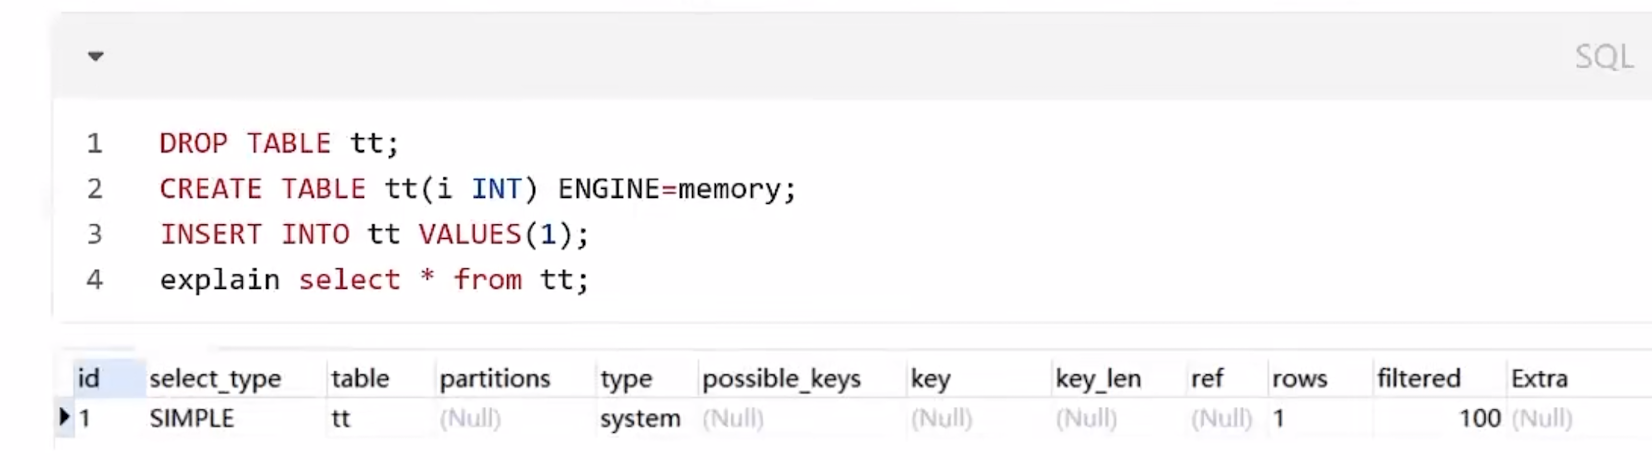
const类型的一种特殊场景,查询的表中只有一行记录的情况,并且该表使用的存储引擎的统计数据是精确的,innodb存储引擎的统计数据不是精确的,虽然只有一条数据但是type类型为all;
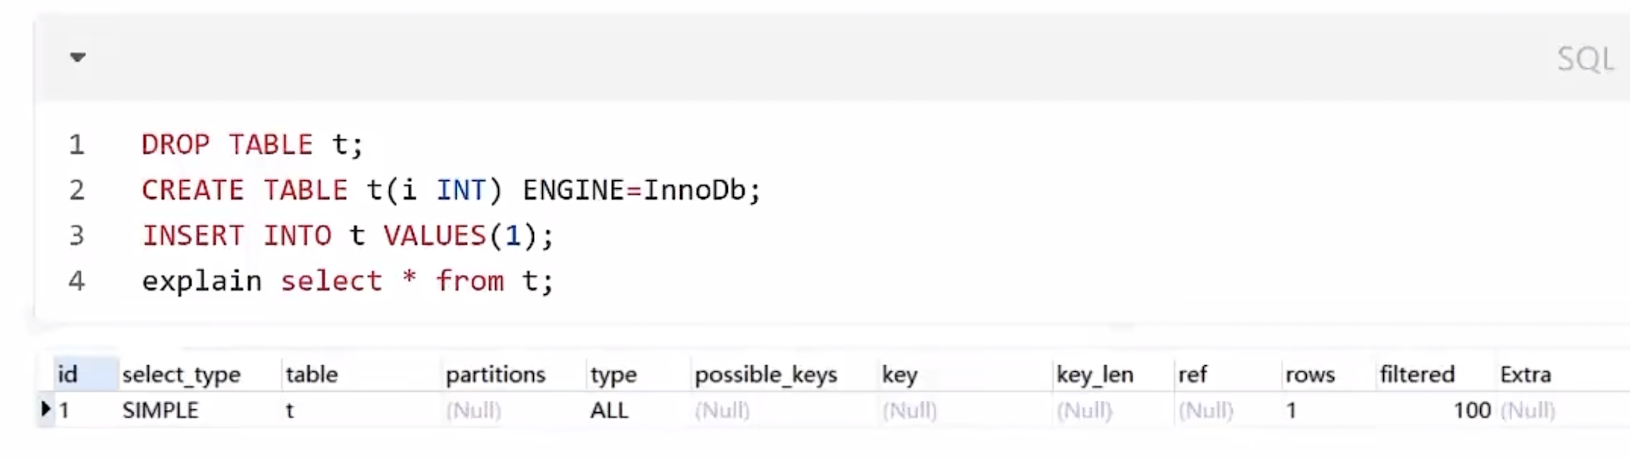
Memory存储引擎的统计数据是精确的,所以当只有一条记录的时候type类型为system
const
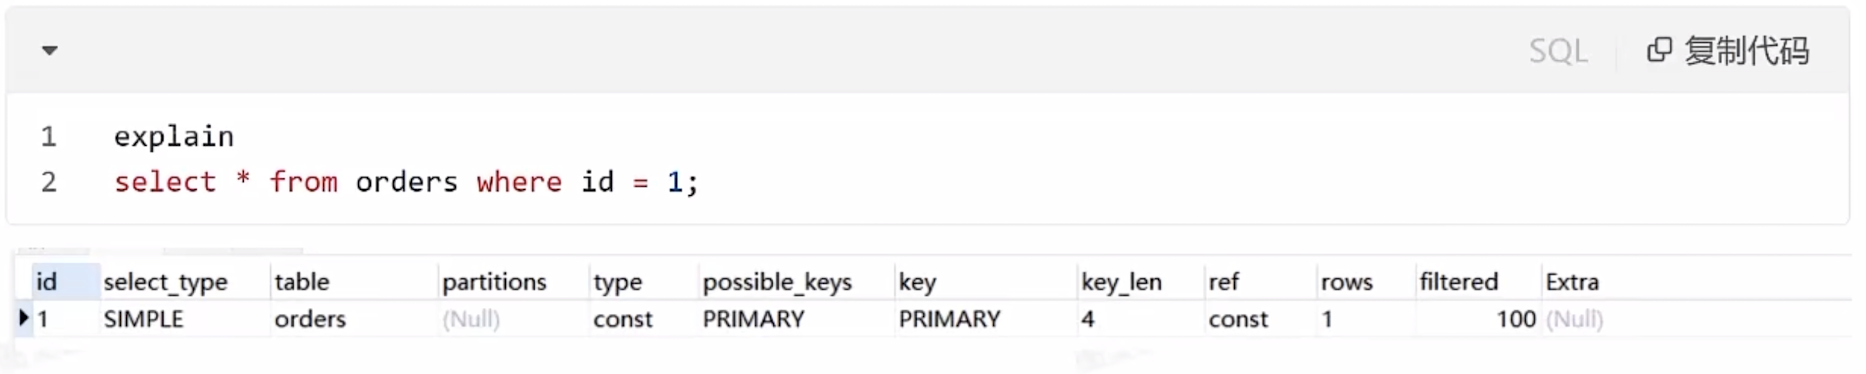
基于主键或唯一索引查看一行,当mysql对查询某部分进行优化,并转换为一个常量时,使用这些类型访问转换成常量查询,效率高
eq_ref
基于主键或唯一索引连接两个表,对于每个索引键值,只有一条匹配记录,被驱动表的类型为eq_ref

ref
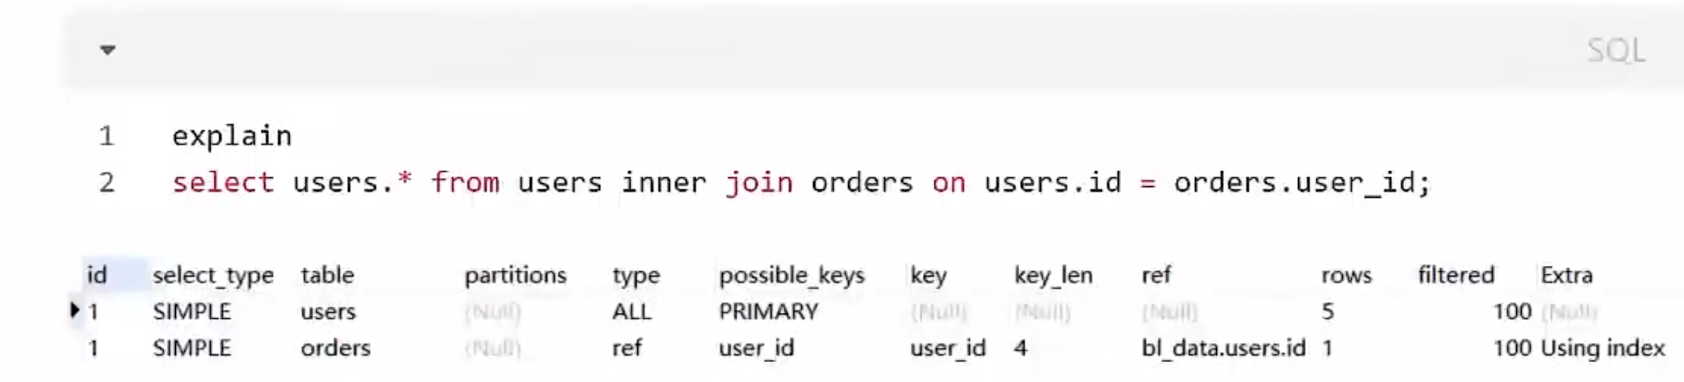
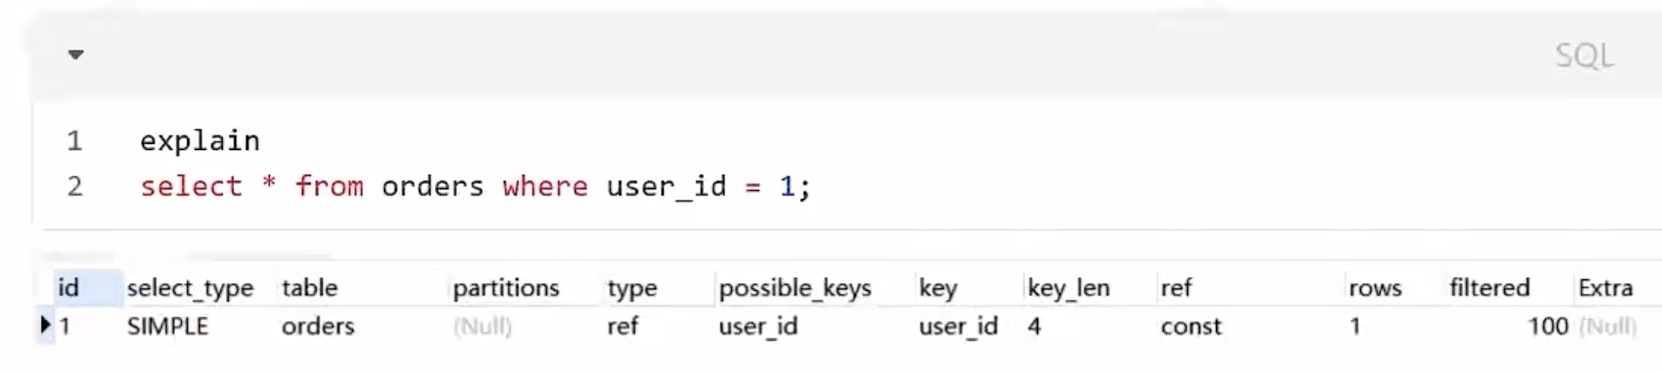
基于非唯一索引连接两个表或通过二级索引列与常量进行等值匹配,可能会存在多条匹配记录
- 关联查询,使用非唯一索引进行匹配
- 简单查询,使用二级索引列匹配
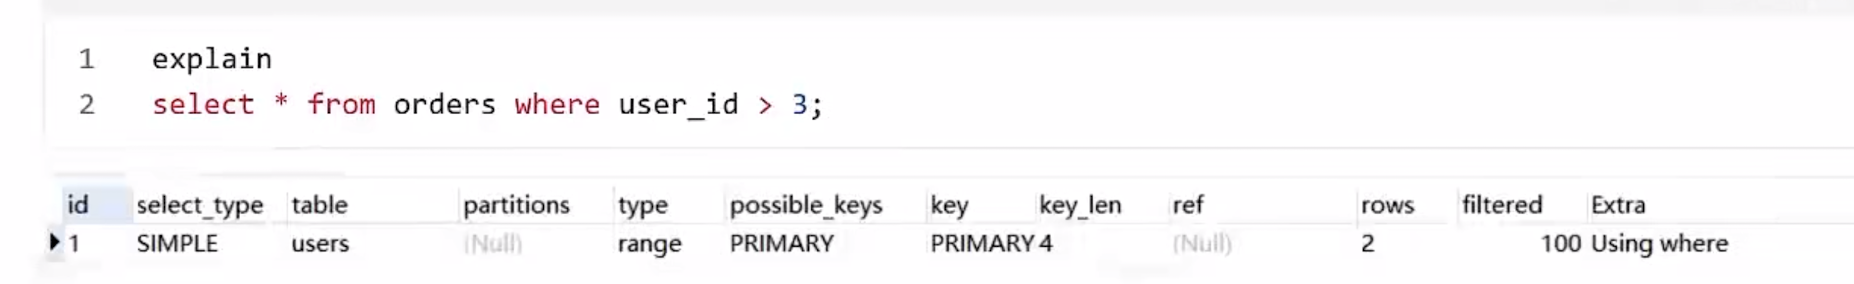
range
使用非唯一索引扫描部分索引,比如使用索引获取某些范围区间的记录
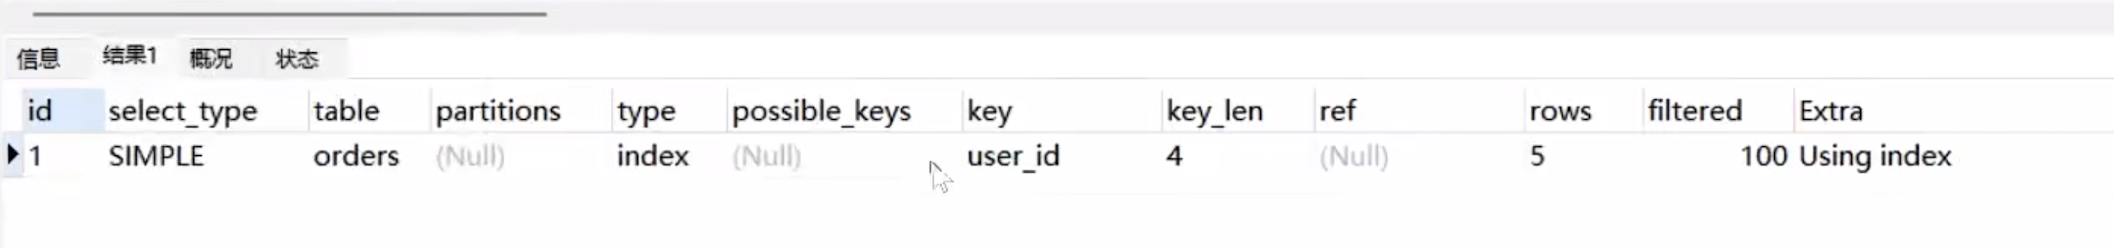
index
扫描整个索引就能拿到结果,一般是二级索引,这种查询一般为使用覆盖索引
explain
select user_id from orders;
all
扫描整个表进行匹配,即扫描聚簇索引树
Null
mysql优化过程中分解语句就已经可以获取到结果,执行时甚至不用访问表或索引
explain
select min(id) from users;